Aero Realtime
Fully Aligned Input–Output Streams for Low-Latency Streaming Multimodal Generation
A 4B realtime multimodal model that places video, audio, silence, and language on one causal clock—so perception never pauses for generation.
One stream. One clock.
Drag the video or waveform. Every bar is one 80 ms audio chunk and one model output slot. Dim slots are <|rt_pad|>: the model chooses silence.
No turn boundary.
Conventional systems alternate between input and output. Aero appends both to the same KV-cached sequence.
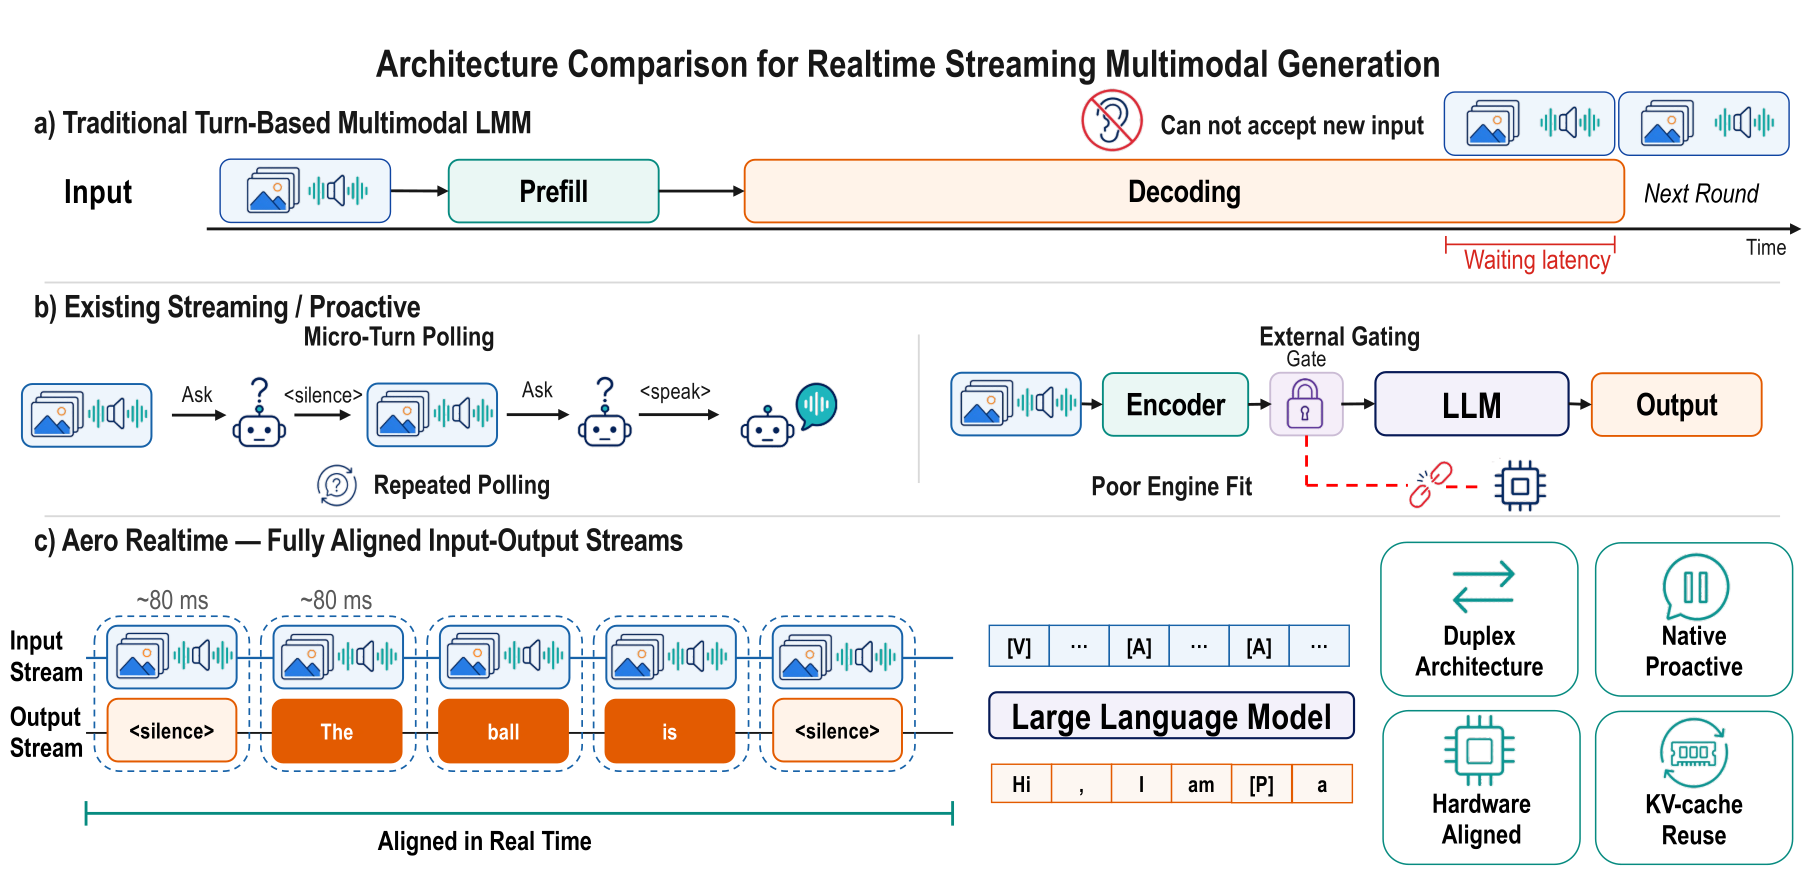
Silence is a token,
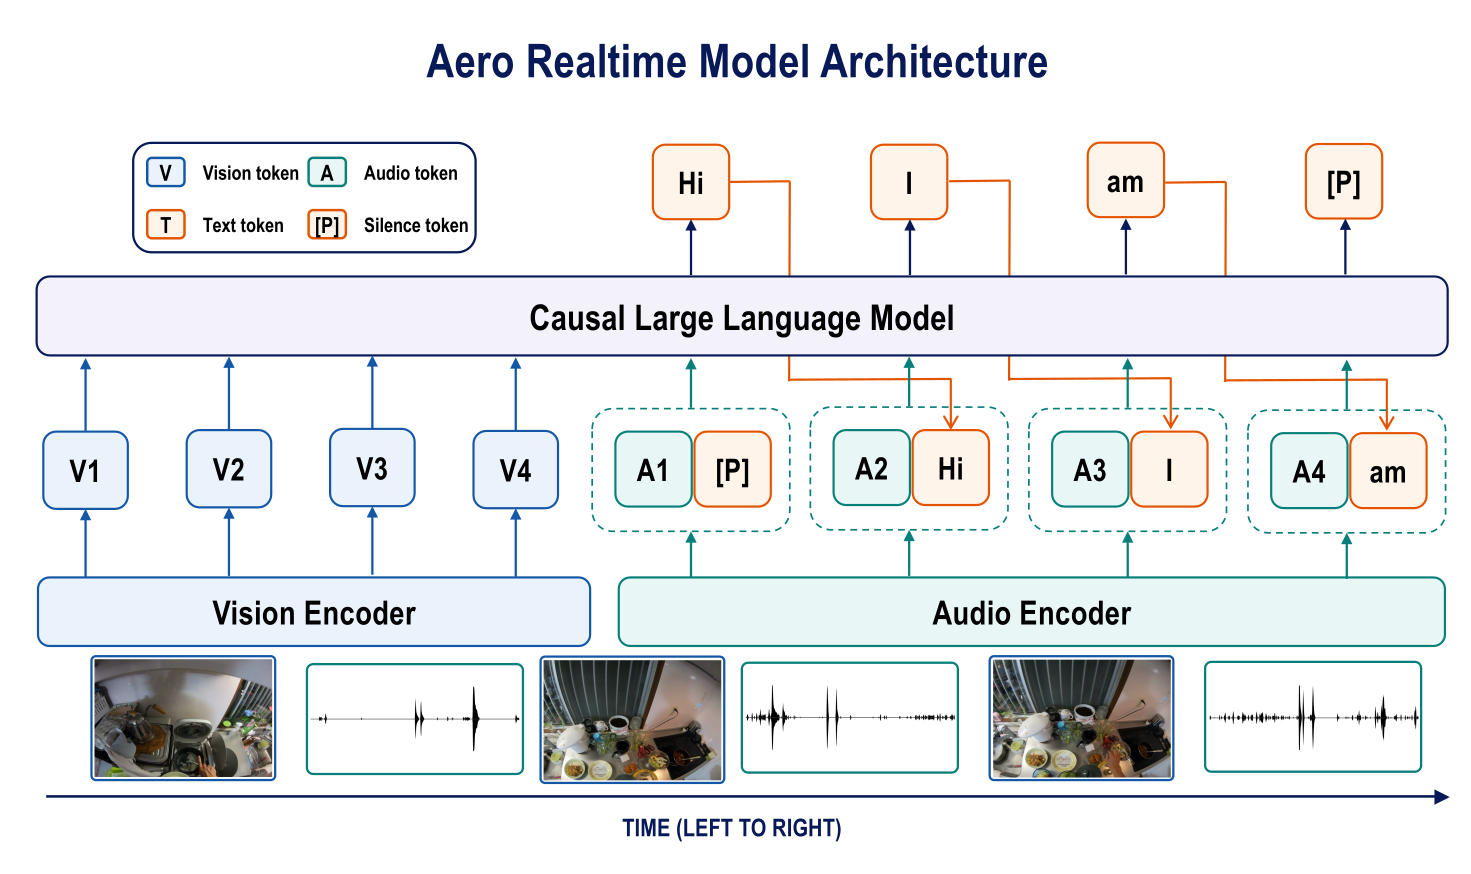
not a separate gate.
At slot t, the audio state is fused with the preceding output embedding. The same language-model head predicts a lexical token or [P], jointly learning when and what to generate.
- Continuous audio-video input
- Native proactive policy
- Cache-valid delta inference
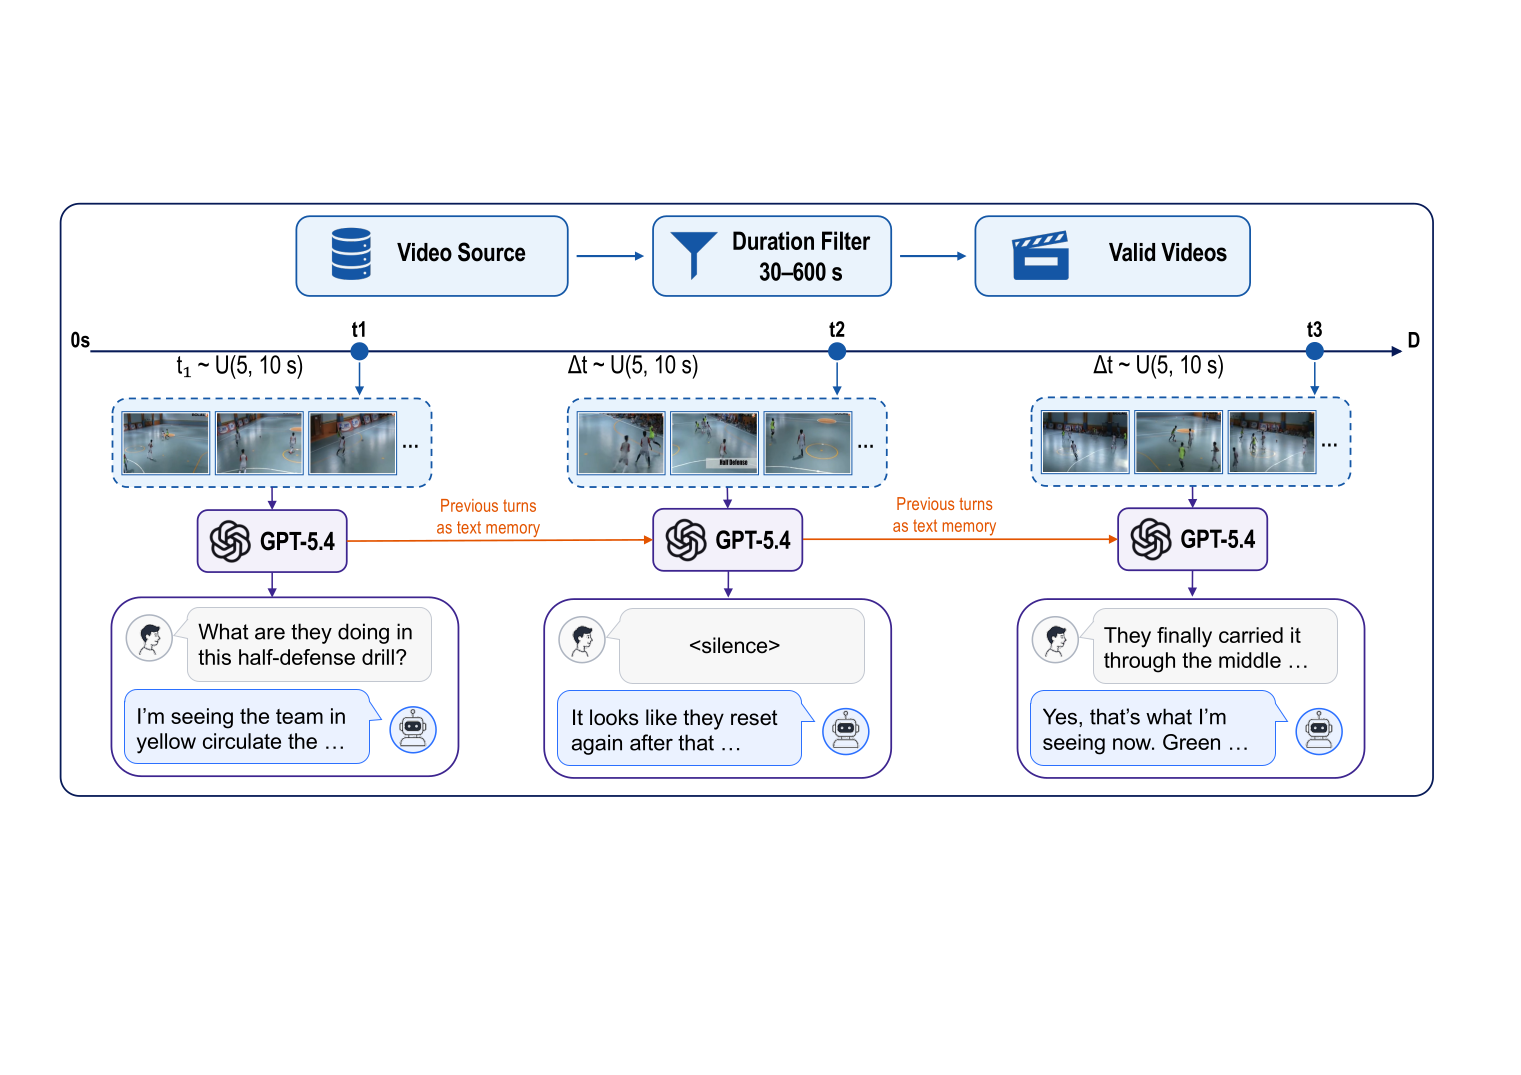
Realtime supervision,
packed at scale.
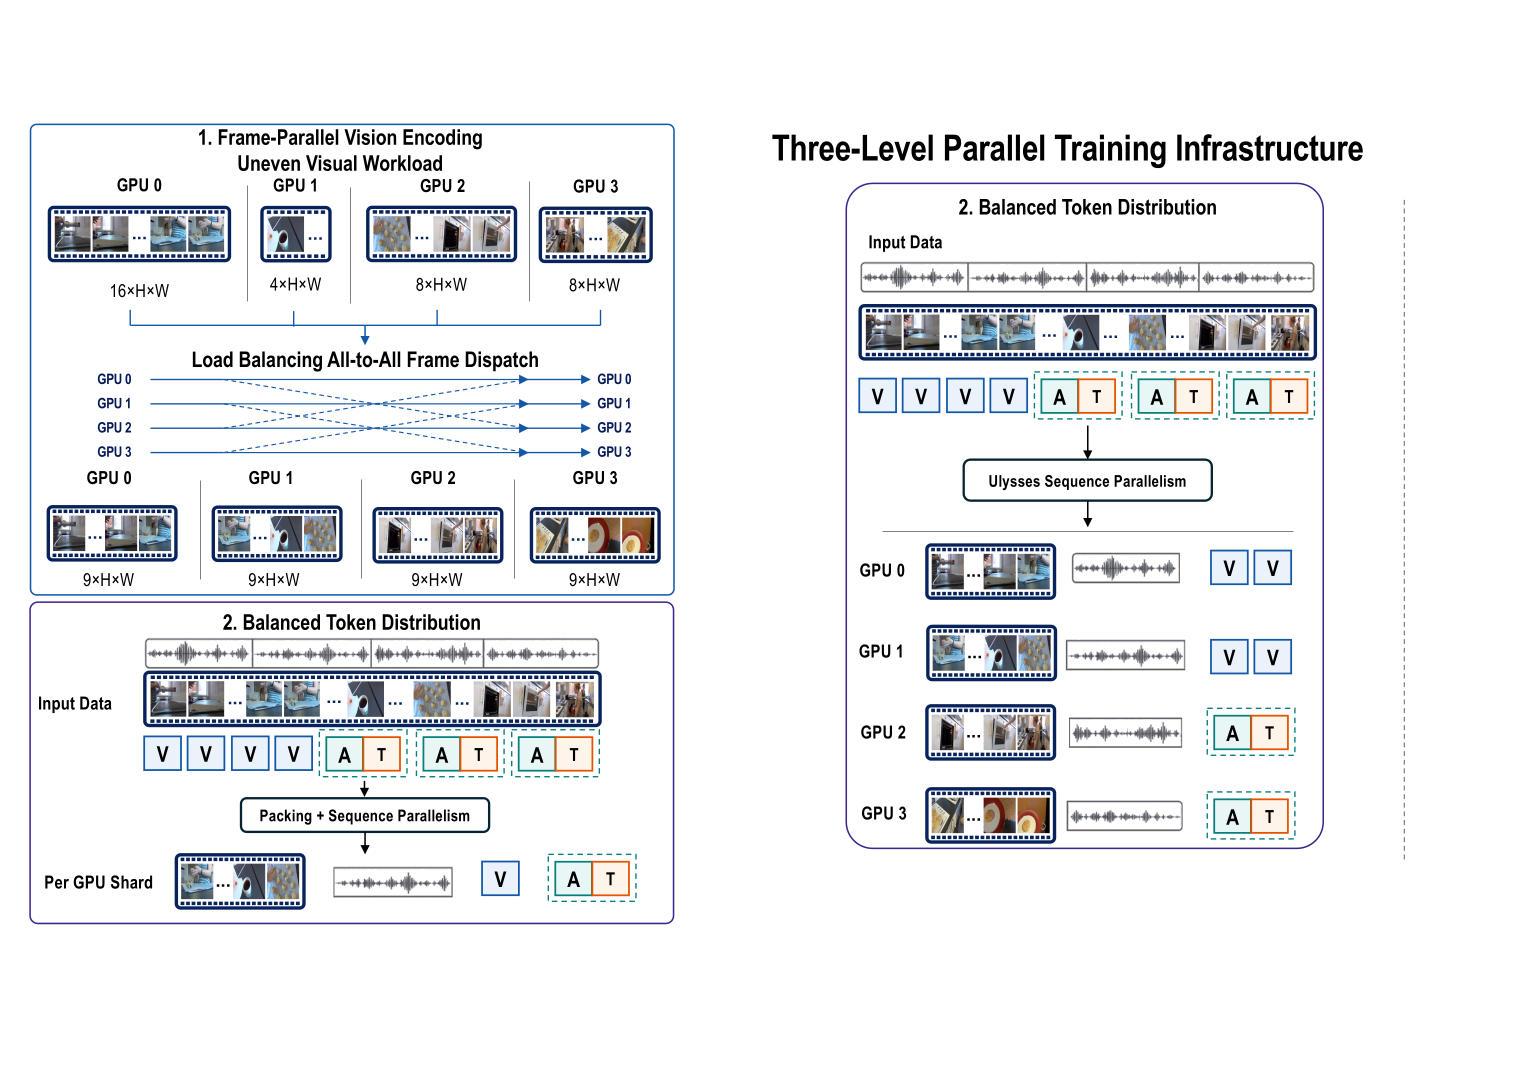
Time-aligned QA is unified with conventional video instruction data, then trained with modality-aware three-level parallelism.
Always on time.
On four NVIDIA A6000 workstation GPUs, input and output remain overlapped as context grows, keeping the model synchronized with a continuously arriving stream.
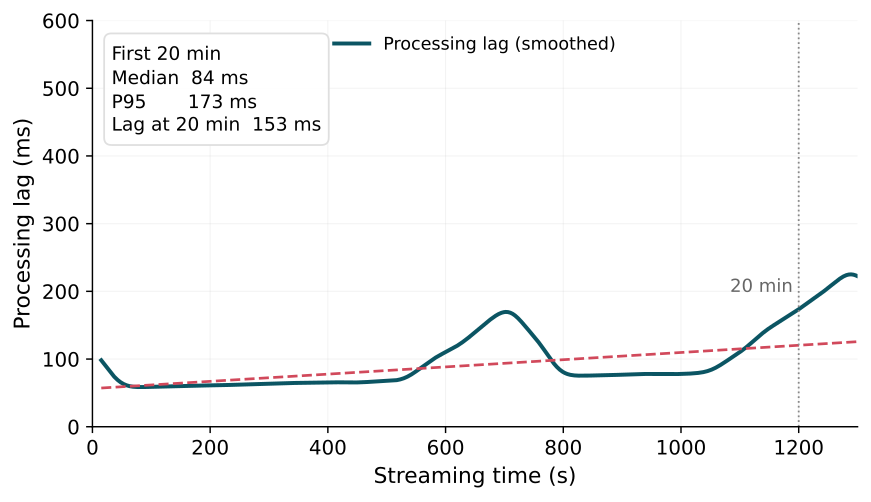
These long-horizon numbers are measured on four 48 GB NVIDIA A6000 workstation GPUs—not datacenter accelerators. Aero is an architectural exploration that trades lexical bandwidth for truly duplex, natively proactive multimodal interaction.
Citation
If this project helps your work, please cite Aero Realtime.
@misc{aero_realtime_2026,
  title = {Aero Realtime: Fully Aligned Input-Output Streams for Low-Latency Streaming Multimodal Generation},
  author = {Aero Realtime Team},
  year = {2026},
  howpublished = {\url{https://github.com/kcz358/aero-realtime}}
}